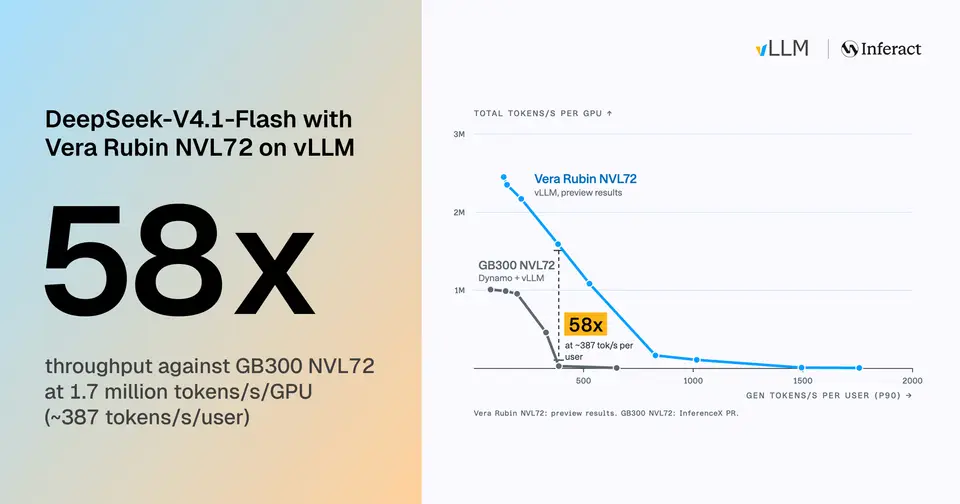
ReadDeepSeek-V4.1-Flash on Vera Rubin NVL72: 58x Throughput vs. GB300 NVL72 at 387 tokens/s#Vera Rubin NVL72#performance-engineeringvLLM BlognewsNov 12, 2026
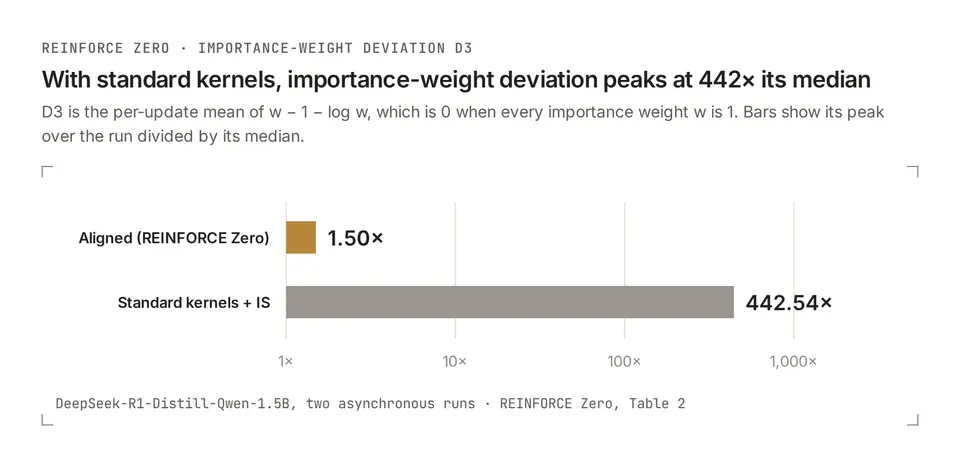
ReadZero Mismatch, Simple Async RL: REINFORCE Zero, DeepSeek-V4.1 and Kimi K3.1#LLM optimization#asyncvLLM BlogarticleNov 6, 2026
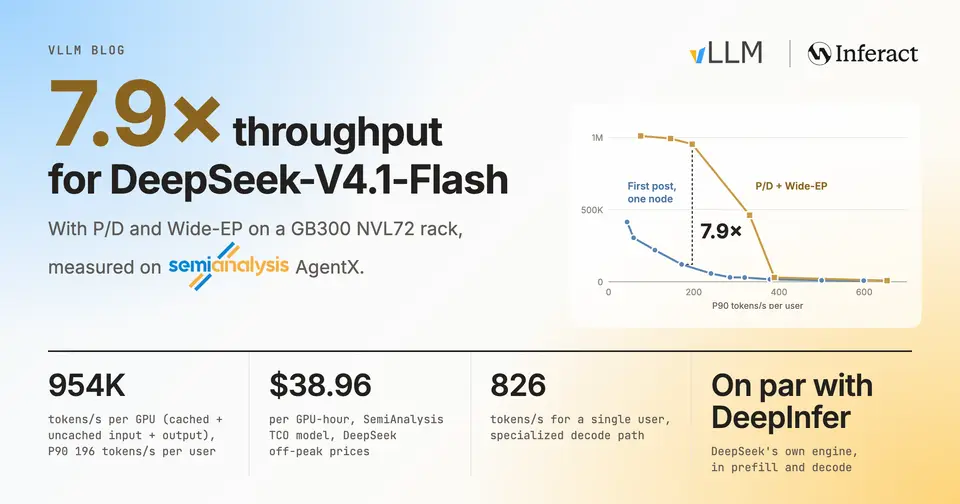
ReadServing DeepSeek-V4.1-Flash at Scale: vLLM Matches DeepInfer and Scales to GB300 NVL72#vllm#GB300 NVL72vLLM BlogarticleOct 23, 2026
ReadMiniMax launches M3.1 Flash model, says it cuts AI agent costs by 70%#LLM optimization#Artificial IntelligenceSiliconANGLEnewsOct 19, 2026
ReadDeepSeek releases updated V4.1-Flash model it says completes tasks faster#Large Language Model#releasesSiliconANGLEnewsOct 18, 2026

 devfeed.