ReadNetwork Contention State Aware Dynamic Optimizer for Accelerator Collective Communication Libraries#Multi Agent Systems#NCCLarXiv: Distributed ComputingarticleNov 10, 2026
ReadCharacterizing CUDA Locality Domains on Blackwell GPUs#CUDA#GPU optimizationarXiv: Distributed ComputingarticleNov 6, 2026
ReadConfigure, Certify, and Operate Kubernetes GPU Clusters with NVIDIA DSX OS#AI Infrastructure#gpu monitoringNVIDIA DevelopertutorialNov 5, 2026
Readflash-comm: Self-Synchronizing Collective Communication for LLM Decoding#LLM optimization#NCCLarXiv: Distributed ComputingarticleNov 5, 2026
ReadDual-Node NVIDIA DGX Spark over Tailscale: A Remote-Access Testbed for Distributed LLM Training and Cyber-Threat-Intelligence Fine-Tuning#distributed-training#DGX SparkarXiv: Machine LearningarticleNov 4, 2026
ReadDiagnose Distributed AI Workload Failures with NVIDIA Attribution#AI Infrastructure#distributed-trainingNVIDIA DevelopertutorialNov 2, 2026
ReadMaking Kubernetes AI-Ready for NVIDIA Vera Rubin on Day One#NVIDIA Vera Rubin#Vera Rubin NVL72NVIDIA DeveloperarticleNov 2, 2026
ReadThe Endgame of FSDP Communication: Layout-Aware Collectives on Copy Engines, RDMA, and NVSwitch#rdma#Distributed Systems & Parallel ComputingarXiv: Distributed ComputingarticleOct 30, 2026
ReadAuto repair for Together GPU Clusters: from GPU fault to healthy node#Distributed Systems & Parallel Computing#NCCLTogether.aiarticleOct 27, 2026
Read5 Lessons from Building a Multi-plane Network Fabric for Agentic AI#AI Networking#AI InfrastructureCoreweave Blog PostsarticleOct 22, 2026
ReadEngineered for Agentic AI: NVIDIA HGX B300 on CoreWeave Cloud#Agentic AI#NvidiaCoreweave Blog PostsreleaseOct 22, 2026
ReadBitdeer AI Brings NVIDIA Minerva's AI-Native AIOps For Maximizing AI Factory Yield#AIOps#AI in IT operationsBitdeer AI CloudreleaseOct 22, 2026
ReadvLLM Support for NVIDIA Vera Rubin NVL72: 7.8x Throughput over GB200 NVL72#vllm#NVIDIA Vera RubinvLLM BlogarticleOct 9, 2026
ReadHow DOCA GPUNetIO Unifies GPU-Initiated Networking Across the NVIDIA Software Stack#gpudirect rdma#DOCANVIDIA DeveloperarticleOct 6, 2026
Read755GB to 395GB: How Bitdeer AI Halves GLM-5.3's GPU Footprint#Mixture of Experts (MoE)#quantizationBitdeer AI CloudarticleOct 5, 2026
ReadModal Clusters are generally available#Distributed Systems & Parallel Computing#rdmaModalreleaseOct 1, 2026
ReadValidate GPU Cluster Readiness Before AI Workloads Land#AI Platform#KubernetesNVIDIA DeveloperarticleSep 23, 2026
ReadSimplifying Model Serving Across Multiple GPUs with NVIDIA TensorRT Multi-Device Integration in NVIDIA Dynamo-Triton#TensorRT#Dynamo-TritonNVIDIA DevelopertutorialSep 21, 2026
ReadFault tolerant distributed training on Amazon EKS using NVRx#NCCL#Amazon Elastic Kubernetes ServiceArtificial IntelligencetutorialSep 16, 2026
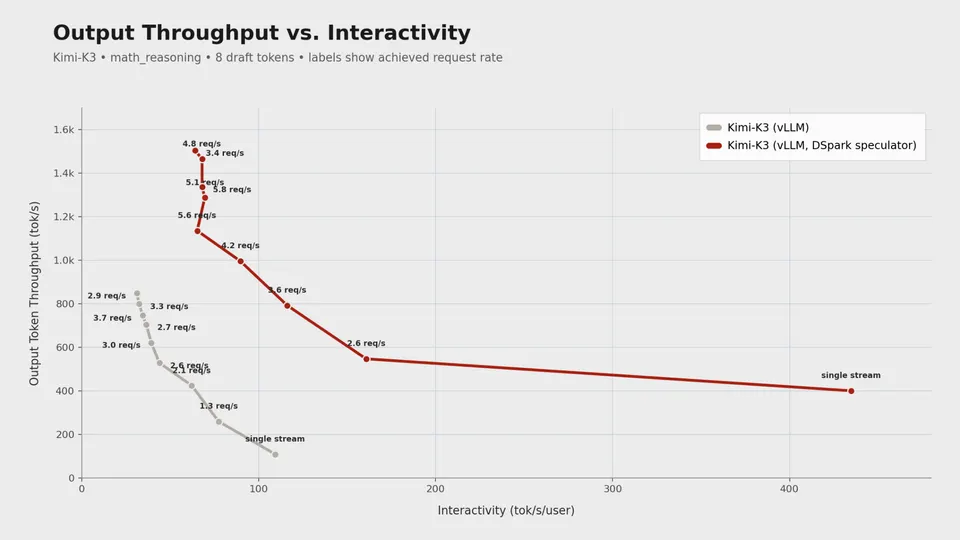
ReadHow Speculators and Mooncake enabled multi-node DSpark training for Kimi K3#Large Language Model#Multi-GPUvLLM BlogarticleSep 15, 2026
ReadAsync GRPO with LoRA across HF Jobs: a bucket, a proxy, and no NCCL#lora#grpoHugging FacearticleSep 10, 2026
 devfeed.