ReadAudio8-TTS-Realistic-Air: Edge0's 0.6B Multilingual Text-to-Speech Model Explained#Speech Processing#voice aiHackerNoonarticleNov 4, 2026
ReadAegisVox: Factorized Privacy and Clinical Preservation for Long-Form Speech#voice ai#asrarXiv: Artificial IntelligencearticleNov 4, 2026
ReadAudio Prompt Injection: What Voice Agents Hear That Text Guardrails Miss#prompt injection#voice aiCheck Point BlogarticleOct 29, 2026
ReadVoice AI in vogue: Nvidia releases new open transcription model#voice ai#NemotronTechCrunch | AI News & Artificial IntelligencenewsOct 28, 2026
ReadNVIDIA Nemotron 3.5 Transcribe and Granary v2: Intelligent Multilingual Transcription You Can Prompt and Adapt#Nemotron#voice aiHugging FacereleaseOct 28, 2026
ReadFrom Voiceprints to User Entities: Online Speaker-Memory Construction for Multi-User Spoken Agents#voice ai#BenchmarkarXiv: Artificial IntelligencearticleOct 28, 2026
ReadBetter speech synthesis for audiobooks#Speech Processing#voice aiAmazon Science homepagearticleOct 23, 2026
ReadMicrosoft’s new voice AI can start working out what you want before you finish speaking#voice ai#Conversational AIThe New StacknewsOct 23, 2026
ReadBeyond Naturalness: Probing Automated Text-To-Speech Evaluators on Linguistically Grounded Dimensions#voice ai#Large Language ModelarXiv: Artificial IntelligencearticleOct 23, 2026
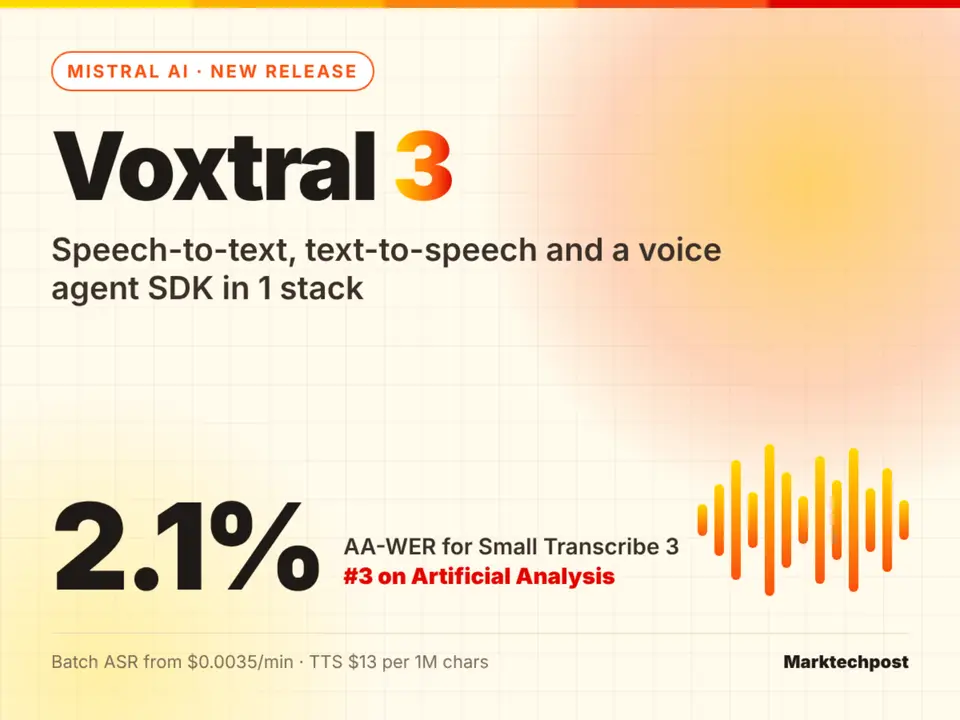
ReadMistral AI Releases Voxtral 3: Speech-to-Text, TTS and a Voice Agent SDK#voice ai#asrMarkTechPostnewsOct 21, 2026
ReadSteering intonational tunes in text-to-speech synthesis#voice ai#Speech ProcessingarXiv: Machine LearningarticleOct 21, 2026
ReadTTS-Q: Speaker-Aware Post-Training Quantization of Text-to-Speech Diffusion Transformers#quantization#Post-training optimizationarXiv: Machine LearningarticleOct 21, 2026
ReadNEW GUIDE: CircuitPython Text to Speech#CircuitPython#Speech ProcessingAdafruit IndustriestutorialOct 19, 2026
ReadFish Audio Releases Drama 3, a 35B Open-Weight MoE Text-to-Speech Model#voice ai#mixtralMarkTechPostnewsOct 14, 2026
ReadVoice AI startup Modulate raises $25M to bring audio-native models to more developers#voice ai#livekitSiliconANGLEnewsSep 28, 2026
ReadDeploying real-time personalized speech with Qwen3-TTS on Amazon SageMaker AI#Artificial Intelligence#Amazon SageMaker JumpStartArtificial IntelligencetutorialSep 25, 2026
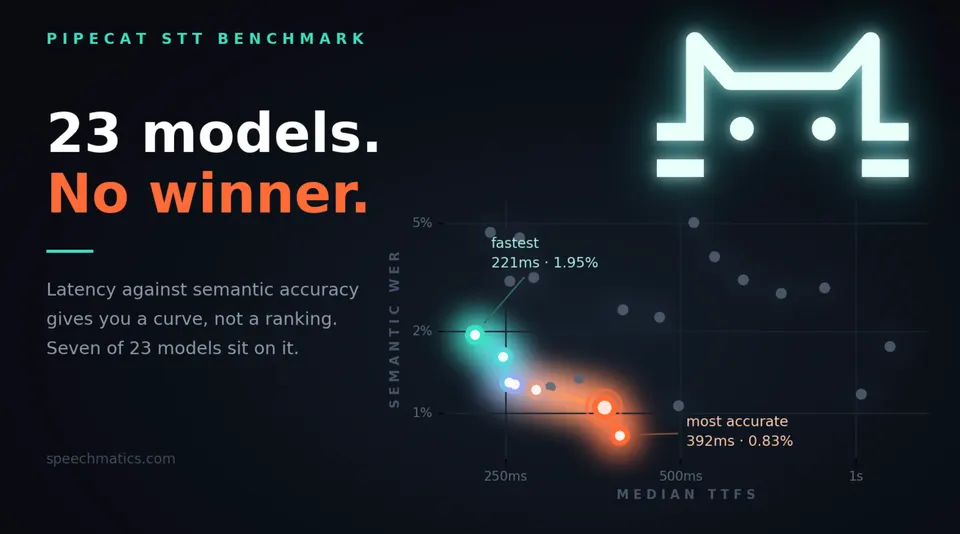
ReadPipecat Benchmarked 23 Real-Time STT Models for Voice Agents. There Isn’t One Winner.#asr#BenchmarkHackerNoonarticleSep 24, 2026
ReadGoogle Releases Self-Service Voice Replication Through the Gemini API#API#Google AIThe New StacknewsSep 24, 2026
ReadUS Developers: You Can Now Shop Seeed Studio Products at Micro Center#Jetson#Internet of thingsSeeed StudioreleaseSep 24, 2026
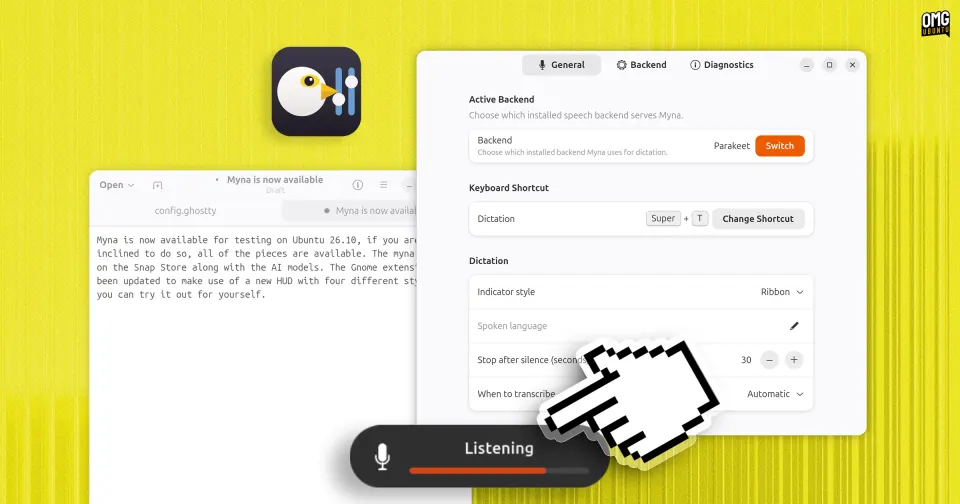
ReadHow to test Ubuntu’s Myna local AI dictation tool#Ubuntu#Artificial IntelligenceOMG! UbuntututorialSep 24, 2026
ReadGoogle launches two benchmark-topping speech generation models#Google#voice aiSiliconANGLEnewsSep 24, 2026
ReadHow to Test and Fix Voice AI Agent Prompts with Twilio Conversation Relay and Cekura#AI Agent#voice aiTwiliotutorialSep 24, 2026
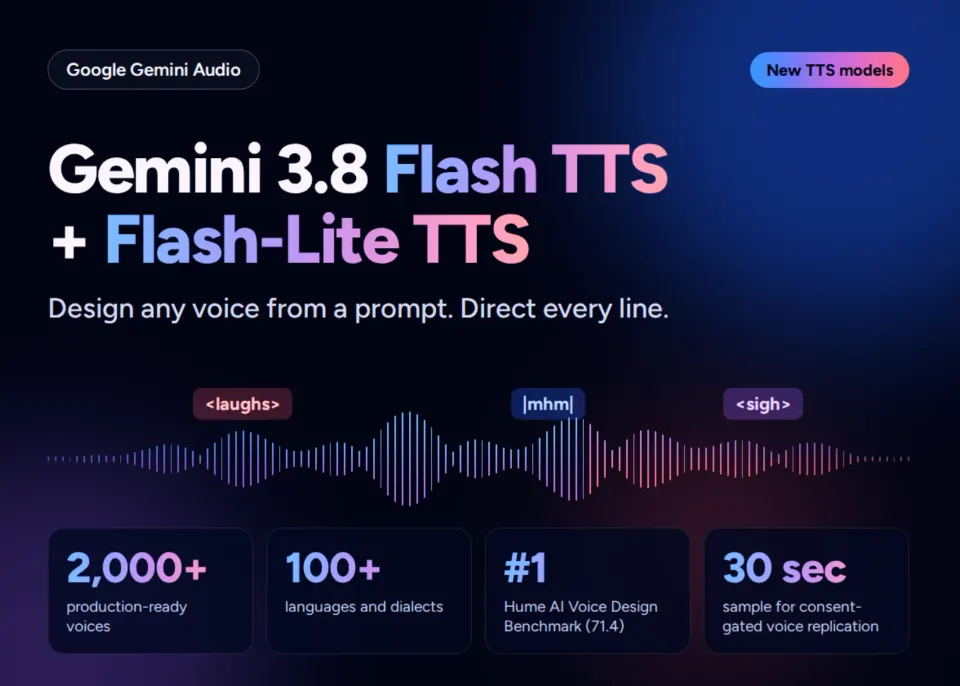
ReadGoogle Releases Gemini 3.8 Flash TTS and Flash-Lite TTS With Prompt-Based Voice Design#voice ai#releasesMarkTechPostreleaseSep 23, 2026
 devfeed.